
If your application updates a database and publishes events, keeping those operations in sync is a challenge. A service can commit a database transaction, then crash before the corresponding event ever gets published.
The transactional outbox pattern makes that specific failure impossible. It guarantees the event is delivered, not just attempted. It's become a foundational pattern in event-driven architecture, where services depend on reliable event delivery to stay in sync.
When events get lost in distributed systems
Imagine a customer places an order. Your application saves the order to the database, then publishes an OrderCreated event so your inventory, billing, and shipping services can take over.
The problem is that those two actions don't happen simultaneously. If your application crashes after saving the order but before publishing the event, the order exists, but the rest of your system isn’t alerted. That's the dual-write problem: One part of the operation succeeds while the other fails, creating a delivery failure that can leave downstream services permanently out of sync.
How the outbox pattern guarantees delivery
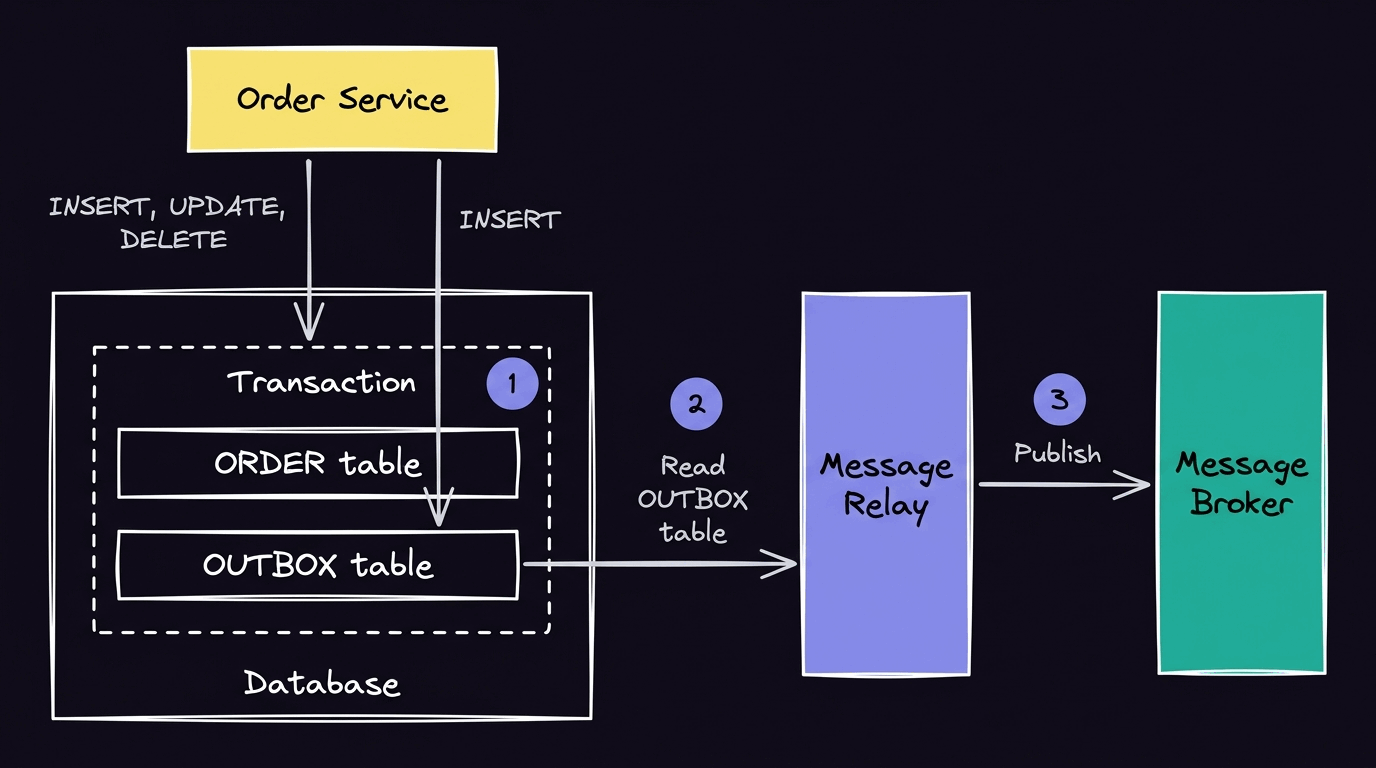
The fix is to write the database change and the event in the same transaction. If the transaction succeeds, both the business data and the event are saved. If it fails, neither is.
The application doesn't publish the event immediately. Instead, it stores the event in an outbox table alongside the business data. A separate message relay reads that table and publishes each event to the message broker. If the broker is unavailable or the publish fails, the relay simply retries. Because the event is already stored safely in the database, retrying doesn't risk losing data or creating inconsistencies; it just delays delivery until it succeeds.
Building the relay in an automation workflow
The outbox table guarantees an event gets recorded, but it doesn’t deliver that event on its own. That's the job of a message relay, which continuously checks for new events, publishes them to a message broker, and retries if something goes wrong. Without that relay, the event never leaves the database. In microservices, the outbox pattern is a common way to make sure every service receives the same committed events, even when individual services or message brokers experience temporary failures.
There are two common ways to detect new events. The simplest approach is polling, where the relay periodically queries the outbox table for unpublished rows. If you need lower latency, change data capture (CDC) reads the database's transaction log and streams new records as they're committed. Polling is easier to set up, while CDC reduces latency at the cost of additional infrastructure. For many teams, polling is the right place to start. As throughput and latency requirements grow, migrating to CDC can improve performance without changing the overall outbox pattern.
You could build that relay yourself, but most teams end up creating redundant, duplicate capabilities. n8n is a workflow automation platform that provides retries, execution history, failure handling, and monitoring right out of the box, making it faster to build a relay that's reliable and easier to operate in production.
In n8n, you can set up publishing from the outbox to a message broker. If you haven’t already set up the message outbound, you may face a dual-write program. Here’s how to solve it:
- Detect new outbox rows: Use a Postgres Trigger node to react to new rows as they're written, or a Schedule Trigger node to poll the outbox table at regular intervals.
- Publish each event: Send the event to your message broker or downstream service. n8n supports several message brokers, such as RabbitMQ and Redis. However, you can also use the HTTP Request node, with built-in retries to handle temporary failures.
- Mark rows as processed: Only update the outbox table after delivery succeeds. Marking a row as processed too early risks losing the event if the relay fails before it's published.
- Alert on delivery failures: If retries are exhausted, use a workflow with an Error Trigger node to notify your team so failed events don't go unnoticed.
- Review execution history: Inspect each relay run to confirm events were delivered successfully or troubleshoot failures.
Once you've built your relay, publish workflows so your team can reuse and maintain the same implementation across projects.
Checklist for guaranteeing delivery in your outbox implementation
The transactional outbox pattern only works if every part of the delivery pipeline is designed to handle failure. A few small implementation mistakes (like marking events as processed before delivery succeeds or letting your outbox table grow indefinitely) can undermine the guarantees the pattern is meant to provide.
Before moving to production, make sure you've covered the following:
- Write events and business data in the same transaction: If you insert the outbox record after committing the business transaction, you can still lose events if the application crashes.
- Mark events as processed only after successful delivery: Wait until the message broker confirms receipt before updating the outbox table.
- Design consumers to handle duplicate events: Even with retries, duplicate delivery is always possible. Make downstream consumers idempotent so they can safely process the same event more than once.
- Choose the right relay strategy: Polling is often the simplest option, while change data capture offers lower latency if your infrastructure justifies the added complexity.
- Monitor stalled events: Set alert on outbox rows that remain unprocessed longer than expected so delivery failures don't go unnoticed.
- Archive processed events: Regularly clean up or archive processed rows to prevent the outbox table from growing without bound.
- Preserve event ordering where it matters: If downstream services depend on processing events in sequence, make sure your relay doesn't introduce ordering issues under concurrent workloads.
Building a reliable relay shouldn't mean maintaining a custom worker service. With n8n, you can automate event delivery, monitor every execution, and retry failed deliveries without writing the surrounding infrastructure yourself.
Reliable event delivery starts with the right relay
The transactional outbox pattern solves one of the most common failure modes in distributed systems by making sure database updates and events are committed together. But that guarantee only holds if a message relay reliably publishes every event, retries failed deliveries, and gives you visibility into what happened when something goes wrong. That's what turns an architectural pattern into a production-ready system.
Try n8n Cloud for free to build, run, and monitor your message relay in one place.
FAQ
Can the transactional outbox pattern publish to an Apache Kafka topic?
Yes, a message relay can publish each committed event to an Apache Kafka topic after the database transaction succeeds. The transactional outbox pattern isn't tied to Kafka (it works with any message broker), but Kafka is a popular choice for building scalable, event-driven systems.